Subscribe to our Blog
We're committed to your privacy. SayOne uses the information you provide to us to contact you about our relevant content, products, and services. check out our privacy policy.

Generating table of contents...
Your application shipped. The real work just started.
Most buyers sign an application maintenance contract expecting it to mean that someone will fix issues as they arise. In practice, that expectation covers only a fraction, often around a third, of what a properly scoped maintenance engagement should deliver. The gap between these two definitions is where budgets exceed expectations, the same incident recurs multiple times, and the client relationship deteriorates before the first contract renewal.
This guide outlines what application maintenance services should include, what a well-defined service level agreement (SLA) should guarantee, what the work should reasonably cost, and, a detail most vendor proposals omit, what typically gets left out of the fine print.
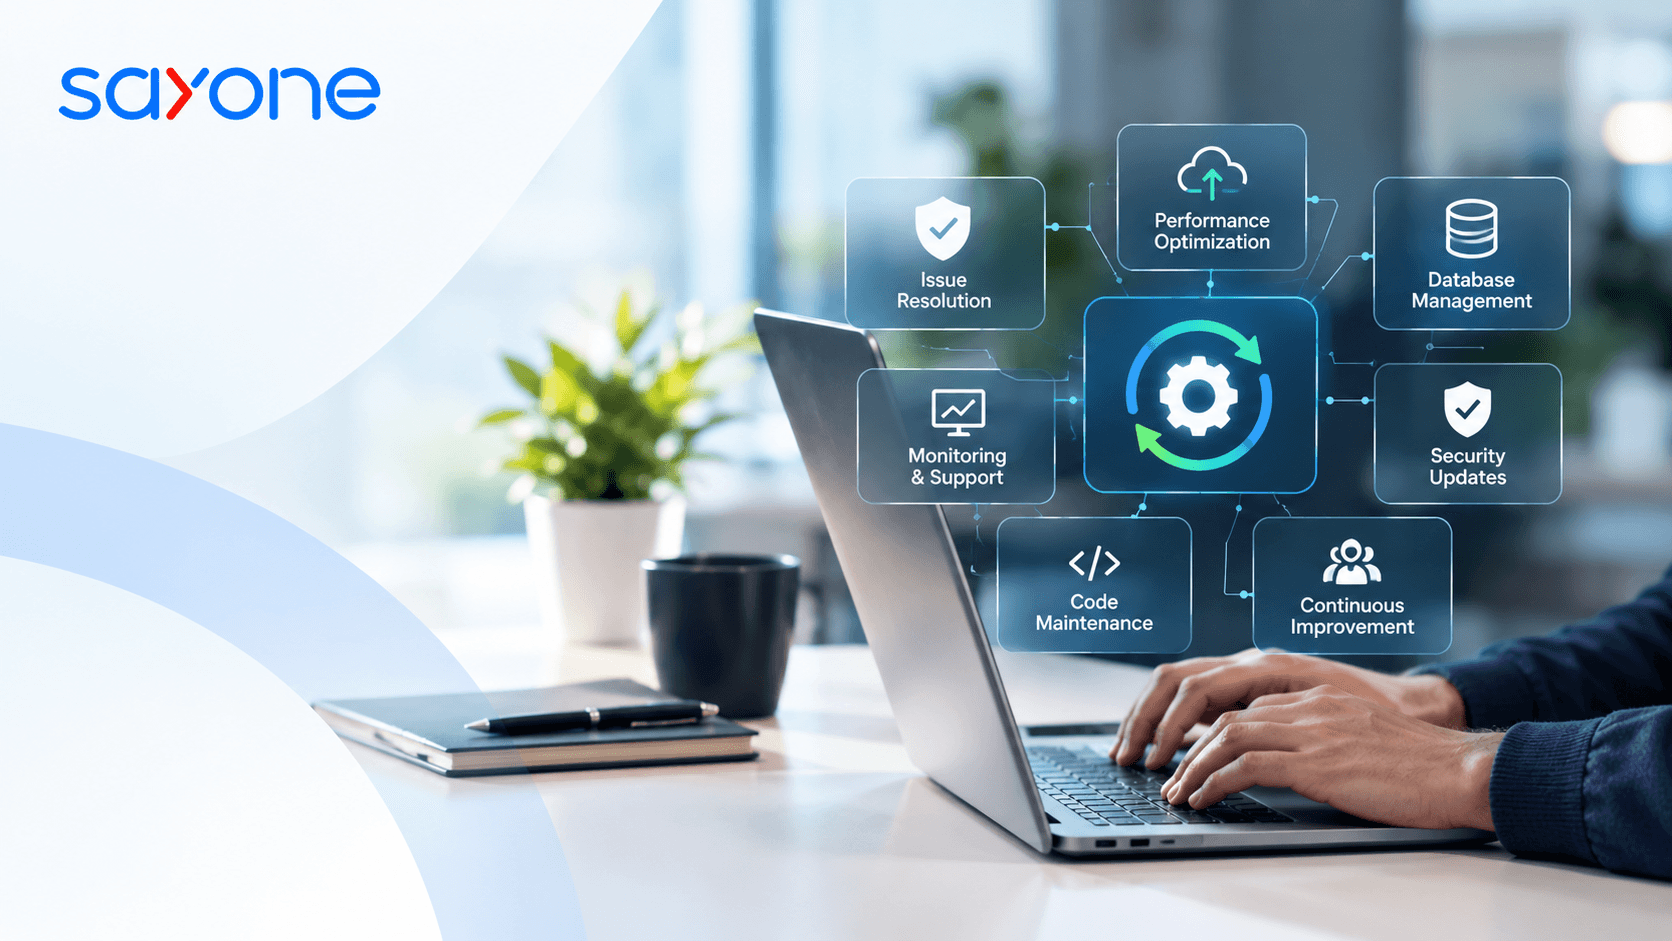
Application maintenance services encompass the ongoing activities required to keep a live software product functional, secure, and current after launch. This includes bug fixes, security patching, performance tuning, dependency and framework upgrades, minor feature additions, and continuous monitoring to identify issues before end users encounter them. Maintenance is distinct from a support desk, which primarily triages tickets, and from a new development engagement, which builds net-new functionality, although a well-run maintenance team typically performs elements of both.
Application maintenance also represents a large and growing category of enterprise IT spend. The global application management services market was valued at approximately $34.40 billion in 2023 and is projected to reach $121.75 billion by 2030, reflecting a 20.2% compound annual growth rate, according to research. This growth indicates that more organizations are treating ongoing application support as a distinct, budgeted discipline rather than an afterthought to the original build contract.
The term "maintenance" is often used loosely by vendors, which is precisely how scope gaps occur. The ISO/IEC/IEEE 14764:2022 standard on software life-cycle maintenance processes provides the industry with a shared vocabulary, and it is worth evaluating a provider's proposal against this standard before signing any agreement.
Corrective maintenance addresses a defect after it has been identified in production. Adaptive maintenance keeps the application usable as its environment changes, for example when a cloud provider deprecates an API version or a mobile operating system introduces a new permissions model. Perfective maintenance improves functionality that already works, such as optimizing a slow query or simplifying a confusing workflow. Preventive maintenance identifies a latent fault before it becomes an incident, similar to how a proactive dependency audit catches a vulnerable library before release. Additive maintenance covers minor, genuinely new features that are bundled into a maintenance retainer rather than scoped as a separate project. Emergency maintenance refers to the unscheduled, urgent fix that stabilizes the system until a proper corrective patch is deployed.
A contract that references only "bug fixes and support" excludes four of these six categories by default. This is not necessarily a problem, but it should reflect a deliberate scoping decision rather than a surprise discovered during an outage.
A service level agreement that promises only to "respond quickly" is not a functional SLA. A usable SLA ties specific severity levels to defined response times, a mean time to resolution (MTTR) target, and an uptime commitment, typically with financial credits applied if the provider fails to meet these targets. The table below outlines a realistic three-tier structure for a mid-sized business application; the specific figures should be adjusted based on how business-critical the system is.
| Tier | Response Time (Critical) | MTTR Target | Uptime Commitment | Typical Monthly Retainer |
|---|---|---|---|---|
| Standard | 4 business hours | 24 hours | 99.5% | $1,500-$4,000 |
| Priority | 1 hour | 8 hours | 99.9% | $4,000-$10,000 |
| Mission-Critical | 15 minutes | 2 hours | 99.95%+ | $10,000+ |
Organizations should ask any prospective provider to share actual incident logs measured against these targets, rather than relying solely on the figures presented in a sales proposal. A provider unable to produce historical MTTR data is effectively indicating that it does not track the metric it has just committed to.
Maintenance budgets are scrutinized during every renewal cycle, typically by comparing the retainer fee against how frequently issues actually occur. This comparison overlooks a key asymmetry: a well-run maintenance engagement is inexpensive relative to the cost of a single serious outage. According to ITIC's 2024 Hourly Cost of Downtime survey of over 1,000 firms, the average cost of a single hour of downtime exceeded $300,000 for more than 90% of mid-size and large enterprises, a figure that excludes litigation or regulatory penalties. A maintenance program that prevents even one such incident annually typically pays for itself several times over.
Most organizations default to whichever delivery model they are already familiar with, which is not necessarily the model best suited to the application. An in-house team offers the deepest institutional knowledge and the fastest informal escalation path, but it is costly to staff for continuous coverage and difficult to keep engaged on routine, ongoing maintenance work. A fully outsourced retainer addresses the coverage and cost challenge but can drift toward generic, ticket-driven support if the provider does not maintain a deep familiarity with the client's specific codebase.
For applications with significant business dependency, a hybrid model tends to perform best: a small internal owner who understands the product roadmap, paired with a dedicated or fractional outsourced team that carries the day-to-day maintenance workload. SayOne has previously examined how blending outsourcing models across a product's lifecycle tends to outperform a single, rigid engagement type, since maintenance and improvement work typically account for the majority of an application's total lifecycle well beyond the original build project. Organizations still deciding between a dedicated resourcing model and a broader outsourcing arrangement for that ongoing team should review the tradeoffs outlined in dedicated developers vs. outsourcing.
No single percentage applies to every organization, but there is a useful benchmark for how the allocation should trend over time. McKinsey's research on technology budget allocation found that the strongest-performing "deliberate modernizer" organizations keep run-based infrastructure and maintenance costs at least 20% lower than their peers, deliberately reallocating that difference toward change and innovation initiatives, according to McKinsey's technology budget research. In practice, this means the healthiest maintenance budgets are actively reduced over time through automation, improved monitoring, and cleaner code, rather than renewed at a flat rate year after year.
For most mid-complexity business applications, a reasonable planning range is 10% to 20% of the original build cost annually for standard maintenance, increasing for applications with extensive integration surfaces, strict compliance obligations, or mission-critical uptime requirements.
Two variables influence that range more than any other factor: the age of the codebase and the number of external integrations it depends on. A five-year-old application built on a since-deprecated framework version will generally cost more to maintain than a comparable application built more recently, because a greater share of maintenance hours goes toward adaptive work required simply to stay current, rather than toward improvements that are visible to users. Integrations compound this further, since every third-party API the application depends on represents a potential source of unplanned adaptive maintenance whenever that vendor introduces a breaking change.
This is the area most vendor proposals omit, since these gaps are often where margin is quietly protected. Proactive monitoring is the most common omission: a contract that only responds to reported incidents is reactive by design, and reactive maintenance is consistently more expensive than the preventive alternative. Security patch cadence is another frequent gap. "We patch when needed" is not a firm commitment; organizations should request a specific cycle time for critical, high, and medium-severity vulnerabilities.
Documentation and knowledge transfer terms are more important than most buyers expect. If a provider's institutional knowledge resides entirely with one engineer, the application has not actually been de-risked; the risk has simply been relocated. Capacity and scale planning ahead of known business events, such as a product launch, a seasonal traffic spike, or a marketing campaign, is frequently absent from standard retainers and should be scoped explicitly. Escalation paths also matter: a maintenance vendor without a clearly defined path beyond first-line support, with measurable commitments at each tier, is offering what one analysis of managed-services evaluation criteria describes as "consulting services with a retainer fee" rather than a true SLA-backed engagement, as covered in SayOne's guide to evaluating managed DevOps providers. Finally, organizations should review exit terms carefully: a provider that makes offboarding and knowledge handover difficult is optimizing for vendor lock-in rather than for the client's outcome.
Organizations should begin by requesting real incident and MTTR data rather than aspirational targets. It is also worth asking which of the six ISO/IEC/IEEE 14764 maintenance categories are actually in scope versus billed separately, how patch cadence is defined by severity rather than described simply as "regular," and what proactive monitoring actually covers, including how often preventive work occurs relative to purely corrective firefighting. Finally, request references from clients running applications of comparable complexity and criticality, ideally ones who have completed at least one contract renewal, since that is typically where the relationship is most thoroughly tested.
It is also worth asking how a provider staffs the engagement on a day-to-day basis. A rotating pool of generalist support engineers will generally take longer to diagnose an unfamiliar codebase than a small, named team that has supported the application for a year or more. In practice, this continuity is typically the single largest driver of MTTR, more significant than any tooling investment.
SayOne integrates SLA discipline, proactive monitoring, and thorough documentation practices into every application maintenance and support engagement rather than offering them as optional upsells. If a current maintenance arrangement cannot answer the questions above with real data, it may be worth seeking a second opinion. Explore SayOne's IT Support & Maintenance Services or get in touch to scope an SLA that holds up under real operating conditions.
A properly scoped engagement covers corrective fixes, security patching, performance tuning, framework and dependency upgrades, proactive monitoring, and small feature additions, not just "fixing things when they break." The ISO/IEC/IEEE 14764 standard groups this work into six categories, and a good provider will tell you upfront which ones are in scope and which are billed separately.
Application support typically means ticket triage and first-line troubleshooting, while application maintenance is the broader, ongoing work of keeping the codebase secure, current, and performant. Most real-world engagements blend both, but a contract that only promises "support" is likely excluding proactive and adaptive maintenance work you will still need.
For most mid-complexity business applications, a reasonable planning range is 10% to 20% of the original build cost annually, rising for applications with heavy third-party integrations, strict compliance needs, or mission-critical uptime requirements. Older codebases on deprecated frameworks generally sit at the higher end, since more of the budget goes toward adaptive maintenance just to stay current.
A usable SLA names specific response times and mean time to resolution (MTTR) targets for each severity level, plus an uptime commitment with financial credits if the provider misses it. As a rough benchmark, mission-critical systems typically warrant 15-minute response times and sub-2-hour MTTR, while standard business applications can reasonably run on 4-hour response and 24-hour resolution targets.
The ISO/IEC/IEEE 14764 standard defines corrective (fixing defects), adaptive (adjusting to environment changes), perfective (improving what already works), and preventive (catching latent faults before they surface) as the core categories, alongside additive and emergency maintenance for new features and unscheduled fixes. Reviewing a proposal against these categories is the fastest way to spot scope gaps before signing.
Patch cadence should be tied to severity, not left as "regular" or "as needed." A reasonable standard is same-day to 48-hour turnaround for critical vulnerabilities, within a week for high severity, and within a normal release cycle for medium and low severity findings.
A clean handover depends on documentation your outgoing provider is contractually required to deliver: architecture notes, credentials, known issues, and institutional context that would otherwise live only in one engineer's head. Build a short parallel-run or shadow period into the transition timeline, and confirm your new provider's onboarding includes a code and infrastructure audit before they take on-call responsibility, so surprises surface before they become incidents.
We're committed to your privacy. SayOne uses the information you provide to us to contact you about our relevant content, products, and services. check out our privacy policy.
We collaborate with visionary leaders on projects that focus on quality